Insight
Which Processes Should AI Agents Actually Take On?
Five signals that surface agent-suitable work without auditing the whole company, what agents do that automation cannot, and where they fail.
September 28, 2026 · Cogya · 8 min read
Last updated: 28 September 2026
Every guide to AI agents ends with the same instruction: audit your workflows, map which processes are rule-based and which involve judgment, then decide.
That is correct and close to useless. Auditing every workflow in an operating business is a project in itself, and the people who could do it are the people already too busy — which is usually why you are considering agents in the first place.
So this article does the opposite. It gives you five signals that surface agent-suitable work without a company-wide audit, and it is honest about where agents are the wrong answer.
What is an AI agent, and how is it different from automation?
An AI agent is a system that decides what steps to take rather than following steps you specified in advance. Traditional automation runs a fixed path — if this, then that — and stops or escalates when something unexpected arrives. An agent reads the situation, chooses an action, and can work with information that has no fixed shape.
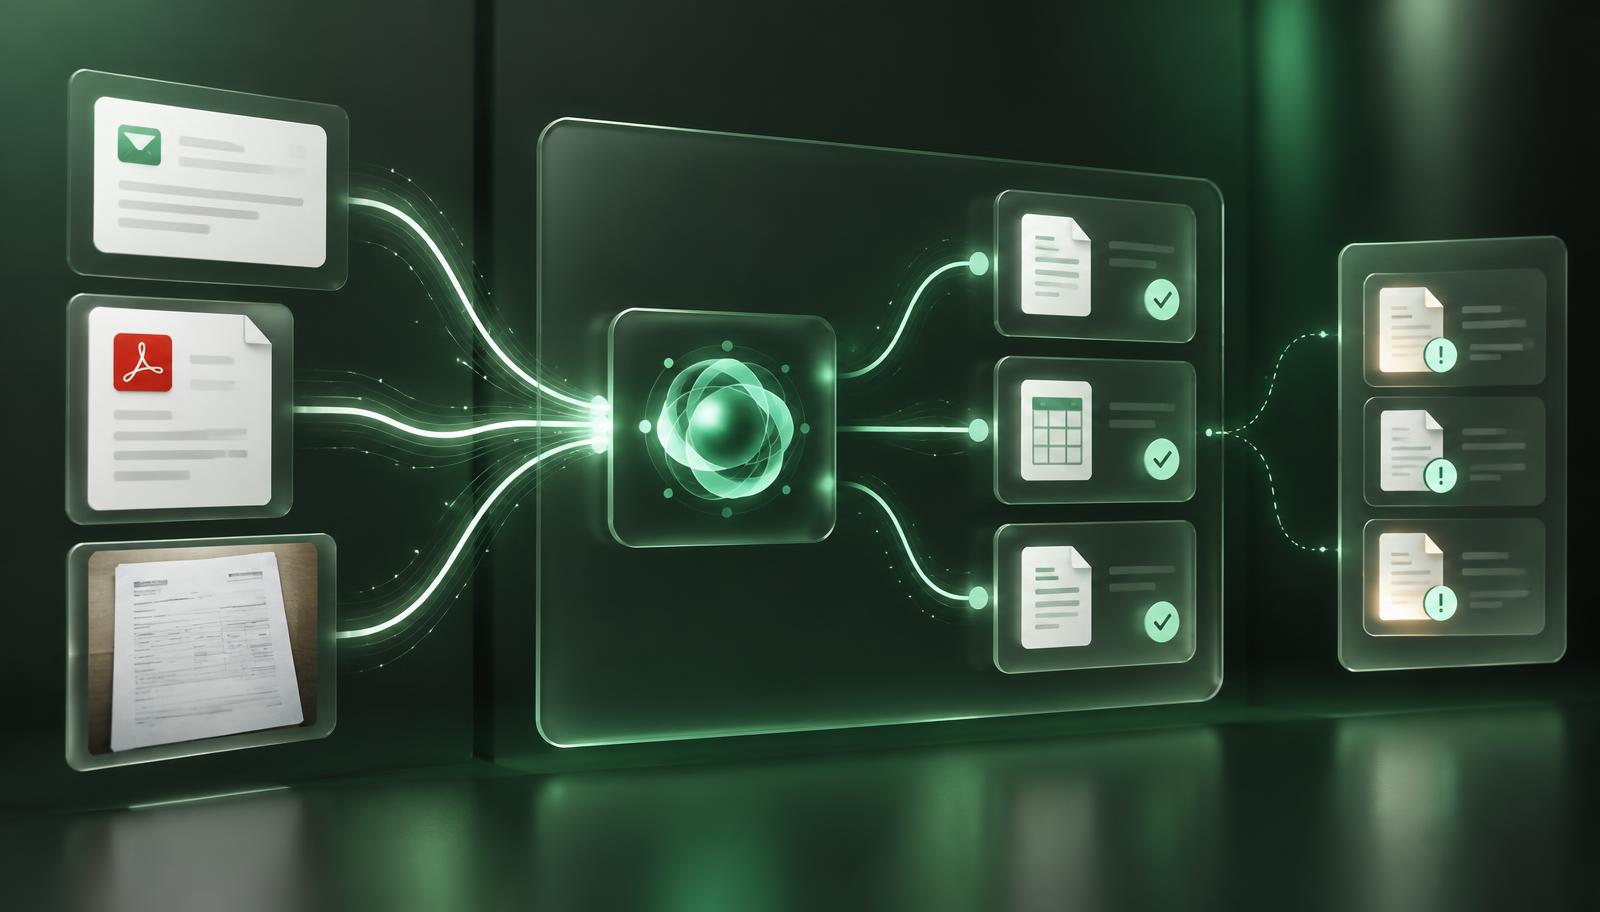
That difference sounds abstract until you put it against a real task. An automation can move an invoice into your ERP once someone tells it exactly where every field lives. An agent can take a supplier's quote as a PDF, an email, or a photograph of a printed sheet, work out which numbers are prices and which are part codes, check them against your catalogue, and escalate the three it is not sure about.
The second is not a better version of the first. It is a different tool, appropriate to a different kind of work, and considerably harder to validate.
Which processes actually suit an agent?
Agent-suitable work has three properties at once: the input arrives in an inconsistent shape, the steps vary depending on what the input turns out to be, and a human currently absorbs that variation by making small judgments all day. Remove any one of the three and something simpler will serve you better and cost less.
Work that arrives as documents, emails or conversations is the usual candidate, because unstructured intake is exactly what fixed-path automation cannot absorb. So is work where the same nominal task takes four minutes one time and forty the next — that variance is a person compensating for something, and the compensation is the agent's job.
What disqualifies a process is consistency. If the input always has the same fields in the same places and the steps never change, an agent is an expensive way to buy a script that would have been more reliable.
How do you find these processes without auditing the whole company?
You do not look at processes. You look for five signals that each point at a small number of candidates, then examine only those. In practice this takes days rather than the weeks a full audit takes, and it is work a single person can do.
1. Follow the exception queues. Find the places where somebody already handles "the weird ones" — the shared mailbox for non-standard orders, the person everyone forwards unusual contracts to, the spreadsheet of cases that fell out of the main system. Exception handling is the clearest existing marker of variable work that a fixed system could not absorb. Someone has already done the classification work for you, informally.
2. Find the shared inbox. Any address where work arrives as unstructured text or attachments and a person triages it into a system. Shared inboxes are where operations hide their unstructured intake, and unstructured intake is the single strongest agent signal.
3. Ask who gets interrupted most. Not who is busiest — who is interrupted. The person others must stop and ask is holding knowledge that has never been written down, and work is queueing behind their availability. That queue is measurable and it is often the constraint.
4. Look for the second keying. Anywhere the same fact gets typed twice, into two systems, by a human. This is usually an integration problem rather than an agent problem, and it is worth separating early — it is cheaper to fix and it often disappears on its own once systems are connected.
5. Ask what gets skipped when the week is busy. Checks that get dropped under pressure — the second look at pricing, the compliance verification, the reference check — are work the business has already decided it cannot always afford. Those are strong agent candidates because the alternative is not a person doing it well, it is nobody doing it.
Then, and only then, count. Take the three to five candidates those signals surface and measure just those: how often does this run, how long does it take, how many end up in the exception queue. A month of real records for five processes is a few days of work. A company-wide time-and-motion study is a quarter, and by the time it finishes the answer has changed.
One warning about the counting, because it is where this goes wrong. Ask for records, not estimates. People systematically over-report how often they do tasks they dislike and under-report the ones they have stopped noticing, and an agent built on the wrong frequency will return nothing regardless of how well it works.
What does this look like with real numbers?
In a procurement build, the agent-suitable work turned out to be the bid package — variable documents, variable supplier formats, and a team absorbing the variation by hand. Response times fell from 48 hours to 2 hours and pricing errors fell 70%.
That system was built for a procurement organisation operating across the United States and Saudi Arabia, which was spending six weeks assembling a bid package across six to eight people, plus two to three weeks collecting supplier pricing. After the build, bid preparation took two weeks, supplier pricing took five to seven days, supplier pricing discrepancies fell 90%, and reported annual bid capacity rose 40%. The full case is here.
The capacity figure is the one worth noticing. Speed is what gets quoted; capacity is what changed the business, and it rose because rework fell rather than because anyone worked faster.
A second example, in recruitment: for a France-based agency sourcing cybersecurity engineers, candidate matching fell from three to five days to two to three hours and standardised profiles went from 30 to 40 minutes each to seconds, with the agency reporting roughly a 30% improvement in deal win rate. That case is here. Recruiters kept every hiring decision. The agent took the collection, filtering and formatting.
That division is the pattern in both: the agent took the variable handling, the human kept the judgment that carries consequences.
Where do AI agents fail?
Agents fail where nobody owns the exceptions, where the process is contested, and where being wrong is expensive and hard to detect. Each of those is a property of your organisation rather than of the technology, which is why they are missed during vendor evaluation and discovered in month four.
Nobody owns the exceptions. Every agent produces a queue of cases it could not resolve. If you cannot name the person whose job that queue becomes, it grows until people route around the system entirely. This is the most common way a technically sound build stops being used.
The process is contested. If two teams run the same task differently and each believes they are right, an agent cannot settle that. It will encode one version — usually whichever it was shown first — and the other team will distrust its output from day one. Settling the process is internal work, it is unbillable, and it has to happen first.
Wrong is expensive and invisible. An agent that mis-reads a price on one quote in fifty is fine if a human sees every quote, and serious if nobody does. Before deploying, decide what a wrong answer costs and how you would notice. If the answer is "we would find out from the customer", build the checking first.
Agent, automation, or neither?
Choose an automation when the input is consistent and the steps are fixed: it is cheaper, faster to build, and far easier to verify. Choose an agent when the input arrives in varying shapes and a person is currently absorbing that variation. Choose neither when the real problem is that two systems do not talk to each other.
That third case is more common than the agent market admits. If the work is a person copying the same data between two systems, no agent is required — that is an integration, it is cheaper, and it is more reliable. We wrote about where connected systems still are not integrated separately.
And if you are not yet sure which of your processes is even the constraint, the prior question is where a business should actually use AI, which is about finding the bottleneck rather than choosing the tool. For task-level selection once you have found it, which tasks are worth automating covers the narrower decision.
What to do this month
Pick the single strongest candidate from the five signals. Get a month of real counts for it. Write down, in advance, what measure would tell you it worked and what a wrong answer costs. Then decide whether to build, and be willing to conclude that you should not.
The organisations that get value from agents are not the ones that moved fastest. They are the ones that chose a process where variation was genuinely the problem, and where somebody was willing to own the queue afterwards.