Insight
Intelligent Document Processing: Beyond Accuracy
How intelligent document processing works, what it changes in practice, where projects go wrong, and how to choose a first document process.
October 19, 2026 · Cogya · 8 min read
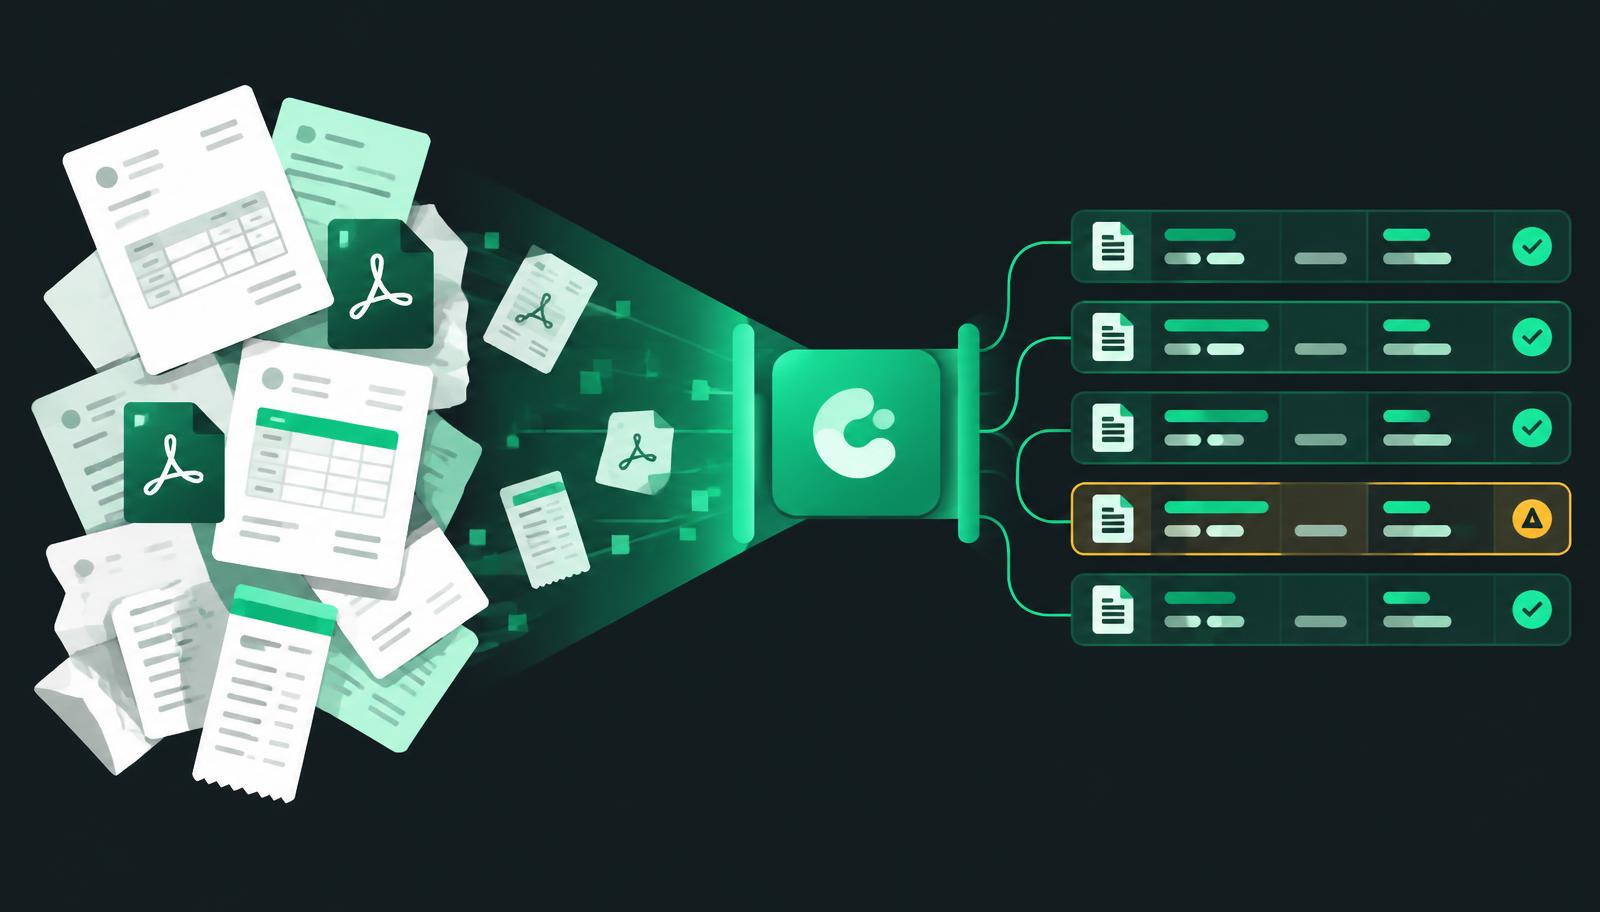
Intelligent document processing is usually sold on reading accuracy: upload a PDF, get structured data back. Accuracy matters, but it is rarely where these projects succeed or fail. They succeed when the extracted data flows into a decision without anyone re-typing it, and they fail when nobody notices the reading quietly getting worse.
What is intelligent document processing?
Intelligent document processing (IDP) uses AI to read business documents such as invoices, purchase orders, quotes, contracts and forms, pull out the information that matters, check it, and pass it to the system where work happens. Unlike older OCR templates, it copes with layouts it has not seen before, handwriting, tables that span pages, and documents that arrive as email bodies rather than files.
How intelligent document processing works
- Capture. Documents arrive from email inboxes, portals, scans or shared folders. The system collects them in one place.
- Classify. It works out what each document is: an invoice, an RFQ, a price list, a delivery note.
- Extract. It pulls out the fields you need, including line items and tables.
- Validate. It checks the result against your rules and data: does the supplier exist, do the line totals add up, does the price match the agreed list.
- Route. Clean results go straight into your ERP, CRM or spreadsheet. Anything uncertain goes to a person with the problem highlighted.
Steps four and five are where the value is. Extraction without validation just moves typing errors from people to software.
What it changes in practice
In a healthcare procurement and bid management build for a company operating across the US and Saudi Arabia, reading and pricing incoming requests was the slow, error-prone step. After the build, RFQ response time went from 24–48 hours to 1–2 hours and supplier price collection from 2–3 weeks to 5–7 days. The more important figures were about correctness: a 90% reduction in supplier pricing discrepancies and an 80% reduction in non-compliance incidents.
The same pattern shows up outside procurement. In an AI recruitment build, preparing a standardised, anonymised client-ready candidate profile went from roughly 40 minutes to seconds. The document was a CV instead of a quote, but the job was the same: read, structure, check, hand over.
Where IDP projects go wrong
- Measuring accuracy on a demo set. Real inboxes contain forwarded chains, photos of paper and documents in several languages. Test on a month of your actual documents.
- Silent drift. A supplier changes their template and extraction drops from 99% to 94% on one field. Without monitoring, nobody notices until a payment is wrong.
- No review queue owner. Uncertain documents pile up when the exception queue belongs to nobody.
- Stopping at extraction. If someone still copies the output into another system, the project has moved the bottleneck, not removed it. That last step is usually API and data integration.
How to choose a first document process
Pick the document type with the highest daily volume, a clear right answer and a measurable cost when it is wrong. Invoices, purchase orders, RFQs and supplier price lists are common first choices. Record how long processing takes today and how often it is corrected, so you can measure the return honestly afterwards. Our guide on which processes suit AI agents explains how to tell when a step needs an AI agent rather than a simpler rule-based tool.
Buy a platform or build a system?
Off-the-shelf IDP platforms work well for standard documents like invoices in common formats. A custom system makes sense when validation depends on your own rules, prices or history, or when the output must feed a decision rather than a database field. In either case, judge it on what happens after extraction. Our pillar page covers what it takes to make an AI automation work.
The short version
Intelligent document processing pays off when reading, checking and routing work together, the output lands where the work happens, and someone watches accuracy over time. Start with one high-volume document type, measure it honestly, and expand from there.